1第 1 步
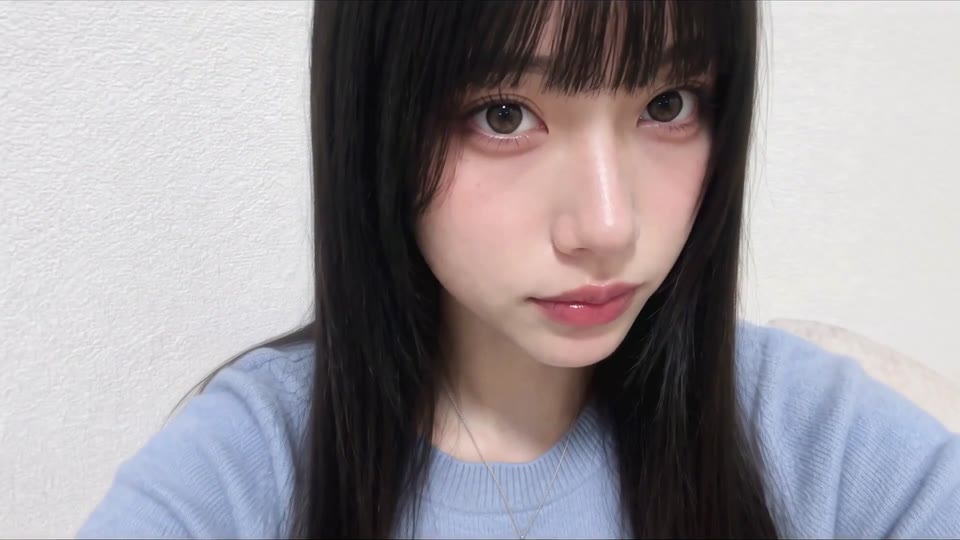
开场中近景
t≈1s · 成片截帧
▸查看完整出图提示词(点击复制区)
复制
成片截帧(非作者参考图/非 Picture 1):固定机位、写实中近景,绫波丽黑长直齐刘海、浅蓝针织衫,白色纹理墙与沙发边,舌头仍在口内,只有细微眼神与头部动作。从作者发布的彩色成片抽帧,仅作跟随拆解;作者未公开静态 Picture 1。
 成片拆解
MiniMax H3 表情驱动短片:一张参考图锁定绫波丽外观,深度动画带动她两次俏皮吐舌。
结构:固定机位 · 两次吐舌表情
看完成片再对照:这条片子靠什么在几秒内抓住人。点时间可跳到成片对应位置。
白墙前的自拍式正面近景,黑长直女孩穿浅蓝针织衫直视镜头,约 3s 就眨眼吐舌——第一个表情来得很快。
吐舌后闭眼说话,约 7s 抬手指戳脸颊,约 8–9s 手指点脸再吐一次舌,比第一次更夸张。
约 11s 手比「一点点」,之后放松微笑对镜头说话,没有额外剪辑。
机位和构图全程不动,只靠脸部表情撑住:两次吐舌卡在约 3s 和约 8.5s。
别急着上视频模型。这个片子的秘密是:先把角色和场景锁死,再一次生成 1 个镜头。
提示词的 subject_definitions 把 <Subject 1>(绫波丽:同一张脸、自然肤质、深色眼睛、黑长直齐刘海、浅蓝圆领针织衫、银项链)和 <Subject 2>(白色纹理墙与沙发边)都绑定到 <Picture 1>,并声明 Picture 1 决定身份、服装、背景、光线、构图和首帧。实际复刻时先准备一张稳定的正面中近景 Picture 1 作为唯一外观基准。注意:作者没有公开这张 Picture 1,本页 refs 只是成片截帧,不能当作原始参考图。
<Video 1> 是带面部运动曲线和舌头轮廓的深度诊断动画,提示词明确“只把它读作动作及其时间的指引;所有可见表面、颜色、面部比例和光照都只来自 Picture 1”。retention_analysis 进一步要求保持原有下颌宽度、脸颊体积和下巴长度,并把动作转译为自然皮肤与针织面料。这是避免模型把灰度深度图、彩色曲线或点直接渲染进成片的关键。
detailed_description 用时间码约束:0.00–3.20 秒舌头在口内;约 3.20 秒伸出、约 4.07 秒收回;约 8.81–10.68 秒第二次伸出、短暂停留并收回;10.68–15.00 秒按原节奏继续其余表情。强调“Two tongue cycles only”,禁止循环、变速、重置和结尾冻结;固定机位与脸部尺度,不改毛衣和墙面;禁止灰度深度图、彩色面部曲线、点、遮罩、文字、图形、断开的舌头和变形手臂。原声音频由作者外部添加,提示词要求不生成对白。
推荐用 GPT Image / 同等图模,比例 4:3。每张点开即可复制完整英文提示词。
t≈1s · 成片截帧
成片截帧(非作者参考图/非 Picture 1):固定机位、写实中近景,绫波丽黑长直齐刘海、浅蓝针织衫,白色纹理墙与沙发边,舌头仍在口内,只有细微眼神与头部动作。从作者发布的彩色成片抽帧,仅作跟随拆解;作者未公开静态 Picture 1。
t≈3.5–4s · 成片截帧
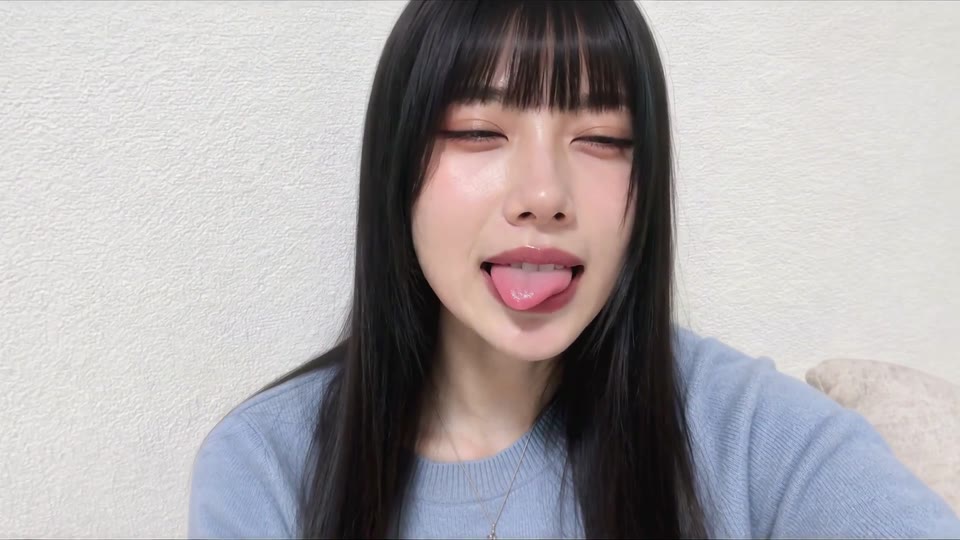
成片截帧(非作者参考图/非 Picture 1):第一轮吐舌(提示词约 3.20–4.07 秒):单眼眨眼、粉色舌头伸过下唇,头部微侧,脸型与服装保持不变。从作者发布的彩色成片抽帧,仅作跟随拆解;作者未公开静态 Picture 1。
t≈7s · 成片截帧
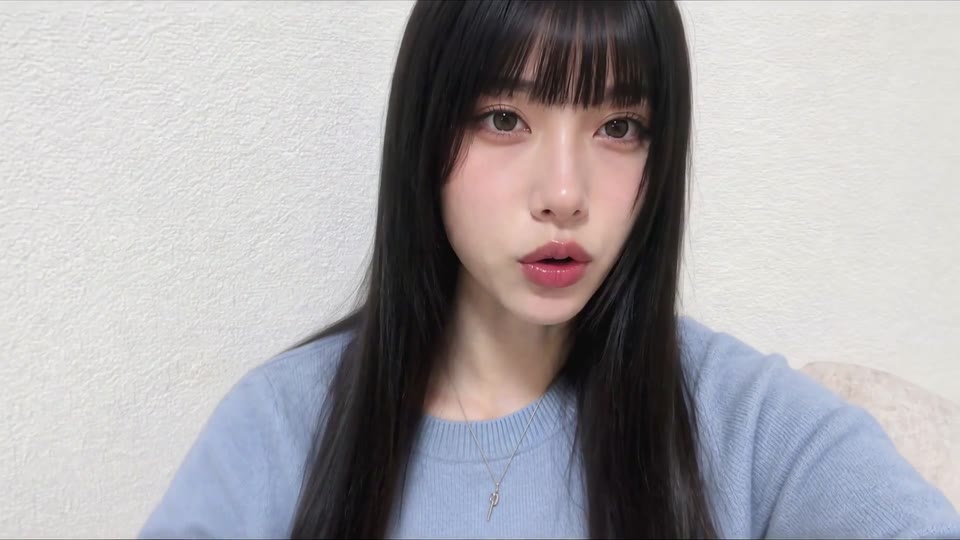
成片截帧(非作者参考图/非 Picture 1):两轮吐舌之间的过渡表情:舌头已收回,嘴唇微张,正视镜头,机位与脸部尺度与开场一致。从作者发布的彩色成片抽帧,仅作跟随拆解;作者未公开静态 Picture 1。
t≈10s · 成片截帧
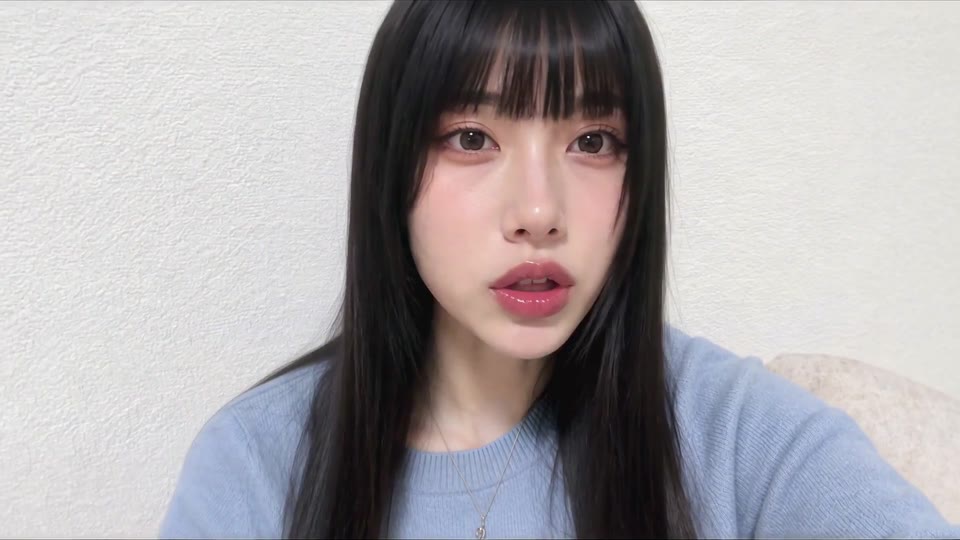
成片截帧(非作者参考图/非 Picture 1):处于提示词第二轮吐舌区间(约 8.81–10.68 秒)附近:嘴部张开、表情变化,肩部和针织袖子保持连续。从作者发布的彩色成片抽帧,仅作跟随拆解;作者未公开静态 Picture 1。
t≈13s · 成片截帧
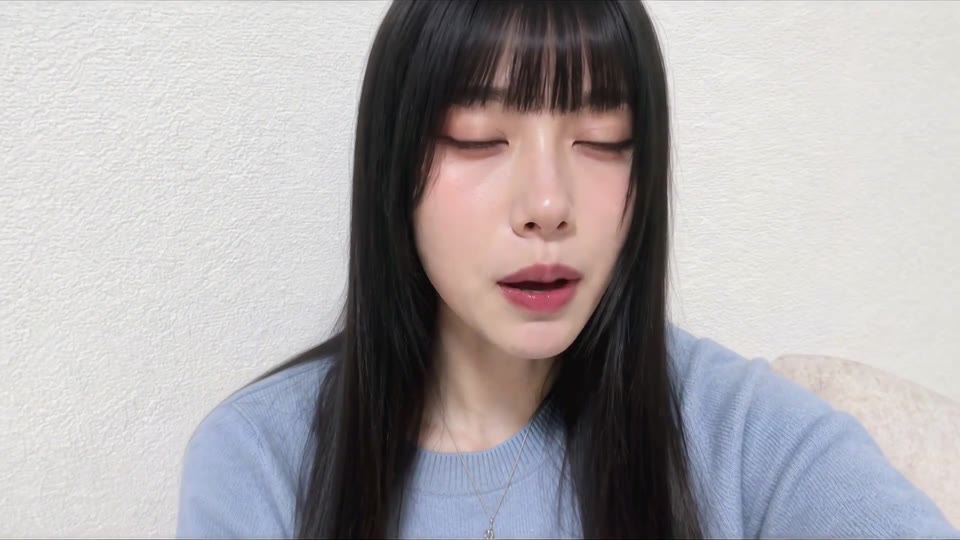
成片截帧(非作者参考图/非 Picture 1):10.68 秒之后的收尾段:闭眼、嘴部细微动作,继续原节奏的眼、嘴、头部表情,无循环或结尾冻结。从作者发布的彩色成片抽帧,仅作跟随拆解;作者未公开静态 Picture 1。
方便你对照成片理解每一镜在干什么。
直接全选复制到 Seedance。@Image 1–5 必须对应上面 REF 01–05。
15s · 16:9 · MiniMax H3 ReferenceToVideo · Picture 1 + Video 1 · 英文完整提示词
subject_definitions:
<Subject 1> is Rei in <Picture 1>: the exact same face, natural skin, dark eyes, straight long black hair with blunt bangs, light-blue crewneck knitted sweater and silver necklace.
<Subject 2> is the white textured wall and sofa edge in <Picture 1>.
<Picture 1> defines identity, clothing, background, lighting, framing and the opening image.
<Video 1> is a diagnostic depth animation with facial motion curves and a tongue silhouette. Read it only as a guide to movements and their timing; all visible surfaces, colors, facial proportions and illumination come exclusively from <Picture 1>.

summary:
[reference generation] A continuous fifteen-second photorealistic medium close-up of <Subject 1>, fixed eye-level camera, landscape 16:9. Keep the same face, black hair, light-blue sweater, necklace and white wall throughout. She makes two brief playful tongue-out gestures at the original reference times, retracts her tongue after each and continues subtle facial expressions. No speech or cuts.

retention_analysis:
Fully preserve <Picture 1> appearance and environment. Change only facial expression and small head movements. Preserve natural shoulders and continuous knitted sleeves. Translate the motion into natural skin and knitted cloth. The visible result is a normally illuminated color photograph of Rei, with her original jaw width, cheek volume and chin length.

detailed_description:
[Shot 1]
Begin from <Picture 1>, then smoothly perform the expression. From 0.00 to 3.20 seconds, perform the initial eye, lip and small head movements with the tongue inside the mouth. Around 3.20 seconds the lips part and a naturally pink tongue extends over the lower lip; it retracts around 4.07 seconds. Continue the intervening expressions and small gestures. Around 8.81 to 10.68 seconds, perform the second tongue extension, brief hold and retraction. From 10.68 to 15.00 seconds, continue the remaining eye, mouth, head and hand gestures at the original pace. Two tongue cycles only, naturally connected inside the mouth. No looping, speed change, reset or forced freeze at the end. Keep the face recognizable and skin realistic. Keep the camera fixed and the original face scale. Do not change the light-blue sweater or white wall. No gray depth-map rendering, colored facial curves, dots, masks, text or graphics. No detached tongue or distorted arms. Original audio is added separately; do not generate speech.
当前是单页静态站:视频 + 指引 + 可复制提示词。后面可以做成多教程列表、账号、收藏提示词、一键复制、手机竖屏版等。